Your data stays on NetApp.
Your AI gets all of it.
- 60+
- Countries with Starburst deployments
- 50+
- Native data source connectors

One query layer, every source
A single SQL and AI access layer across every connected system, cloud, on-premises, or hybrid. Data is read in place, never copied.
Open lakehouse, no lock-in
Open table formats any engine can read, with compute scaled independently of storage. No proprietary rewrite to get in, and none to get out.
Governance that travels with the data
Row and column level access control, masking, lineage, and a full audit trail. The same policy set applies everywhere data lives, including the systems that can never leave the building.
AI ready without a data project
Every agent and application reaches governed data through one access point and returns cited, traceable answers. AI initiatives start from the estate you already have, not a year of pipeline work.
How it works
NetApp holds the data. Starburst makes it answerable.
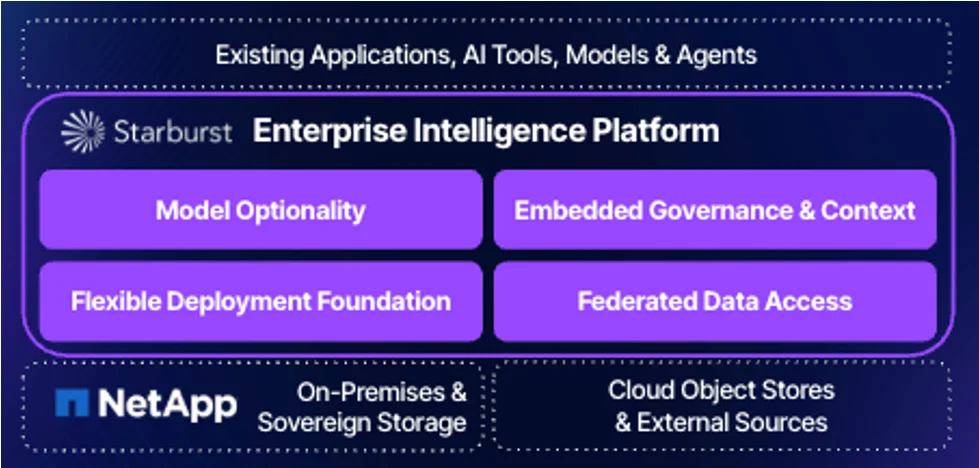
NetApp is the enterprise data foundation, with high-performance storage for structured and unstructured data, on-premises and in every major cloud. Starburst is the governed query and AI layer that reads across it and everything around it, in place.

Enterprise Intelligence Platform
Queried in place. Nothing moves unless you choose to move it.
Where teams start
Modernize in phases. Not in one migration.
Most enterprises arrive here with the same three problems in sequence: legacy platforms they can't rip out, a lakehouse they want to standardize on, and AI work blocked on data access. Starburst and NetApp address them in that order, on infrastructure you already own.
Query what you have, before you replace it
- Read Hadoop, Cloudera, Teradata, and legacy warehouses in place
- Retire ETL pipelines incrementally instead of all at once
- Data stays resident on ONTAP and StorageGRID throughout
- No forced migration, no warehouse-first architecture
Build the open lakehouse on NetApp
- Apache Iceberg and Delta Lake tables on NetApp storage
- Publish reusable, versioned data products instead of extracts
- Compute scales independently of storage
- Open formats: Spark, Flink, and Trino read the same tables
Make the estate AI-ready
- Runs alongside NVIDIA-accelerated inference on the same governed data
- Governed context served to agents over MCP, not raw table access
- AIDA answers business questions with every fact cited to a source
- Policy, masking, and audit applied before data reaches a model
Starburst inside NetApp's AI Data Engine
Beyond the connector-level integration, Starburst technology is being engineered into NetApp's own AI Data Engine, so the federated query and governance layer described on this page is reachable from NetApp's data platform directly.
Structured data is only half of most enterprise questions. Pairing Starburst's federated access to systems of record with NetApp's reach into documents, contracts, and unstructured content on ONTAP is what makes a single grounded, cited answer possible.

Built for AI
Accelerated by NVIDIA, governed by Starburst, hosted on NetApp
NetApp's AI Data Engine is co-engineered with NVIDIA, so the governed, federated data this page describes is already positioned next to the GPUs that put it to work.
- GPU-accelerated queries (Starburst integrates NVIDIA cuDF).
- Data staged next to the GPUs (NetApp FlexCache and SnapMirror).
- Versioned training sets in seconds (NetApp FlexClone).
Why Starburst + NetApp
Hybrid, open, and governed. On infrastructure you already own.
Hybrid by default
One governed layer, not one stack per environment
Hybrid usually means maintaining two of everything: two governance models, two sets of pipelines, two definitions of the same metric. NetApp gives you consistent data services on-premises and in every major cloud; Starburst puts a single query and policy layer over all of it, so a question is answered the same way wherever the data happens to sit.
- Consistent across on-premises NetApp and Cloud Volumes ONTAP in AWS, Azure, and GCP
- One policy set applied across every environment, not duplicated per silo
- Pushdown and caching keep federated queries fast without staging copies
- Structured and semi-structured data read through the same interface
Hybrid footprint
Sovereignty and compliance
Built for data that legally cannot move
Regulated institutions run into the same wall: the analysis is allowed, the data transfer is not. Keeping data resident on NetApp and querying it where it sits removes the transfer from the equation. You get cross-border analytics without the cross-border copy, and an audit trail for every access.
- Sensitive data stays on-premises by design, preserving data residency
- Fine-grained access control and masking enforced at the query layer
- Full lineage and exportable audit logs for every query and retrieval
- Attestations and reports available in the Starburst Trust Center


Proof
Trusted by 10 of the top 15 global banks
How regulated enterprises run Starburst across distributed estates today.
100+
countries
0
data transfers
We needed to analyze transaction data across more than 100 countries for anti-money laundering investigations, without moving data across borders. Starburst made that possible with its federated architecture and data residency controls.
Warehouse, lake
and cloud, unified
We have data in the warehouse, lake, lakehouse, and eventually the cloud. The beauty of Starburst is materializing a view across all those data sources. As we make changes on the back end, we don't have to worry about migration or data movement, because everything is stitched together with Starburst.
See what changes when intelligence reaches all your data.
Start with one business question and one governed path to the answer.